EU AI Act and Performance Reviews: What AI Must Never Decide
 ··4 min read
An assistant that drafts a sentence is a different object, in law, from a system that scores a person. Regulation (EU) 2024/1689 Annex III, point 4(b), is where that difference gets expensive. This is a map for the conversation with your lawyer and, in Germany, with your works council. It is not the conversation.
What point 4(b) actually names
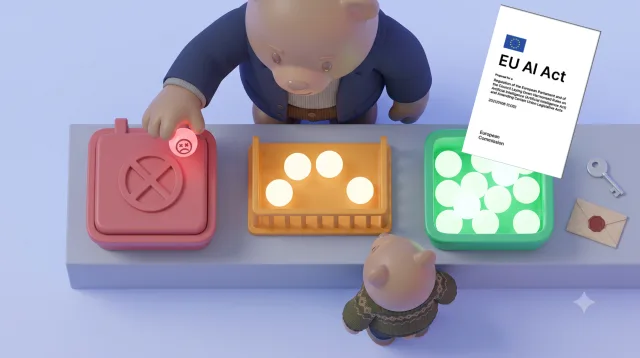
Annex III lists the AI systems that Article 6 treats as high-risk. Point 4 is employment. Point 4(a) is hiring: placing ads, filtering applications, evaluating candidates. Point 4(b) is the job you already have. In the Regulation's words, it covers AI systems intended to make decisions affecting terms of work-related relationships, promotion or termination, to allocate tasks based on individual behaviour or personal traits, or "to monitor and evaluate the performance and behaviour" of people in those relationships.
Read the verb. Monitor and evaluate. A shared doc full of sentences a manager wrote is not on that list. A product that turns those sentences, or the team's Slack, or last quarter's ticket counts, into a score the company then uses is the thing the annex is describing.
Article 6(3) carves some Annex III systems back out, where they do not pose a significant risk, including by not materially influencing the decision. Preparatory tasks can sit in that carve-out. The same paragraph then shuts the door: a system that profiles natural persons is always high-risk. Ranking people, clustering them by "potential," or building a behavioural score is profiling with a friendlier brochure. Do not plan on the carve-out if the feature's job is to sort humans.
Two neighbouring rules are easy to mash together, and they are not the same tier. Inferring emotions at work is prohibited under Article 5(1)(f), already, not filed under "high-risk and complicated." Sentiment ranking of calls, cameras, or chat is that ban when it is reading feelings. A composite performance score is point 4(b). We sorted the tiers, and the dates, in what you can and cannot automate. The scope did not get smaller because a deadline moved.
Why a German works council stalls on the score
Where a works council exists, § 87 (1) no. 6 of the Works Constitution Act gives it a co-determination right over the introduction and use of technical devices designed to monitor the behaviour or performance of employees. If the employer and the council do not agree, the conciliation committee decides. That is not a courtesy review. It is a veto with a procedure.
The fight is rarely "may we store what a manager typed." The fight is the device that watches, counts, or ranks. A dashboard that scores people from ticket volume, chat tone, or a model of "impact" is built to monitor performance. A form a human fills in, with no composite on the other side, is a smaller and more honest ask. It can still be a technical device. Bring it to the council as a form, with a written answer to "what does this calculate," and expect the meeting to be shorter than the one about a ranking.
None of this tells you that your deployment is outside Annex III. Article 6(4) puts the writing-down duty on the provider who claims a system is not high-risk. If you are the company using it, you still want that assessment in a drawer before someone asks.
Four guardrails that keep the draft from becoming the decision
We make SquadBear, so this is a description of what the product does, not a classification. A lawyer classifies the deployment. These are the four boundaries the review module is built around.
Peer answers arrive scrubbed. A manager's assistant can read submitted peer feedback, labelled Peer 1, Peer 2, with a date and no colleague's name. The recipe tells it to use themes and never to quote, name, or guess who wrote them. The person being reviewed does not see peer answers at all.
Upward feedback is air-gapped. Anonymous comments from direct reports are released as counts and unnamed text, and only once enough people have answered (3 or more). No assistant tool reads an upward response or an upward result. The upward form takes no links, because a link can name someone.
There is no composite score. Finished manager ratings show on the round, one review at a time, and they are not averaged. There is no 9-box, no stack rank, and no number that means "this person, overall." A human-picked point on one question is not a score of a human.
The human picks the rating. get_review_context reads the review you are asked to write. save_review_draft stores suggested wording and links that only you can see. The assistant can suggest a point. It cannot set one, and it cannot submit, share, or finish. You tick that you chose every rating, and you submit. Submitting deletes the draft.
Those last two are the Article 6 question in product form. A draft that does not materially decide anything is the preparatory shape. A score that ranks the team is the profile. If a vendor's demo ends on a talent matrix generated from the model's read of the quarter, you are no longer in the preparatory carve-out, whatever the contract calls the feature.
What can you do with the review I am writing in SquadBear, and which steps stay mine? Do not suggest a rating you cannot tie to a specific piece of work.
The management argument for refusing the score in the first place is performance reviews without the theater. Who sees what is the table behind the four boundaries above.
Start free for up to 5 people, or open the demo and look at a finished review before you ask an assistant to touch one.